Monday, October 1, 2018

New Unicode Technical Director

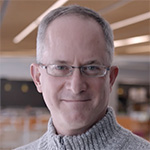
Ken LundeThe Unicode Consortium would like to welcome a new Technical Director, Dr. Ken Lunde.

Ken Lunde has worked at Adobe since 1991, specializing in CJKV Type Development, meaning that he develops East Asian fonts, along with the specifications on which they are based. He architected the Adobe-branded “Source Han” and Google-branded “Noto CJK” open source Pan-CJK typeface families that were released in 2014 and 2017, is the author of “CJKV Information Processing” Second Edition that was published by O’Reilly Media at the end of 2008, and frequently publishes articles on Adobe’s CJK Type Blog. Ken holds BA, MA, and PhD degrees in linguistics from The University of Wisconsin-Madison. Ken has been Adobe’s representative to Unicode since 2006, has been the primary representative since 2015, serves as the IVD Registrar, participates in the Unicode Editorial Committee, and received the 2018 Unicode Bulldog Award.

For the listing of current directors and officers of the Consortium please see Unicode Directors, Officers and Staff

Friday, September 14, 2018

Unicode CLDR 34 alpha available for testing

The alpha version of Unicode CLDR 34 is available for testing. The alpha period lasts until the beta release on September 26, which will include updates to the LDML spec. The final release is expected on October 10.

CLDR 34 provides an update to the key building blocks for software supporting the world's languages. This data is used by all major software systems for their software internationalization and localization, adapting software to the conventions of different languages for such common software tasks.

CLDR 34 included a full Survey Tool data collection phase. Other enhancements include several changes to prepare for the new Japanese calendar era starting 2019-05-01; updated emoji names, annotations, collation and grouping; and other specific fixes. The draft release page at http://cldr.unicode.org/index/downloads/cldr-34 lists the major features, and has pointers to the newest data and charts. It will be fleshed out over the coming weeks with more details, migration issues, known problems, and so on. Particularly useful for review are:
Please report any problems that you find using a CLDR ticket. We'd also appreciate it if programmatic users of CLDR data download the xml files and do a trial integration to see if any problems arise.

Thursday, September 6, 2018

New Japanese Era

A new era in the Japanese calendar is expected to begin on May 1, 2019, following the announced abdication of Japanese Emperor Akihito. This era will be represented in dates by two names: one consisting of a sequence of two existing kanji and one consisting of a new single Japanese character that combines those two. (Similarly, the current era Heisei can be represented by either “平成” or “㍻”.)

The Japanese calendar system and support for era names is essential for important public sector business functions. Therefore, most software distributed in Japan will need to adopt the new era name and add font support for the new character.

The current Heisei era has been in place since 1989 — during the evolution of modern computer systems. Because of this, most software systems have not been tested for such an event. The exact date of the announcement of the new era name is unknown, but current expectations are that there will be a very narrow window for implementing the new era information in IT environments, perhaps less than a month. Until the announcement, dates in 2019 and beyond will continue to be written with the Heisei era name and its year numbering.

To prepare as well as possible for this unprecedented event, the Unicode Consortium has taken the following actions:

  • The code point U+32FF has been reserved for the new era character.
  • Once the new era name is announced, the Unicode Consortium will quickly issue a dot-release (Version 12.1) that will add that character at the reserved code point, U+32FF, with an appropriate character name, decomposition, and representative glyph.
  • Unicode CLDR and ICU are including test mechanisms in the 2018 October releases of CLDR 34 and ICU 63. Systems that use CLDR or ICU (all smartphones, for example) can test using these mechanisms.
  • Systems and applications that do not use CLDR or ICU will need to take similar steps for testing.
The short time window between the actual announcement and the effective date will present challenges to the IT industry. IT systems in Japan will be expected to have the support in place seamlessly. Because of the narrow timeframe and the need to upgrade or patch legacy software, it is important to start now to determine how soon your application/system can add support to your current implementations, stacks, and dependencies.

Thursday, August 23, 2018

IUC 42: Keynote Speaker Announced

Carlos Pallan Gayol

The Advent of Mayan Script Encoding: Mapping the Last Frontiers of Mayan Hieroglyphic Decipherment

Carlos Pallan Gayol
Archaeologist & Epigrapher, Dept. of Old American Studies & Ethnology, University of Bonn


Mayan hieroglyphs rank among the most visually complex writing systems ever created. Deciphering them has entailed a 200+ year scholarly quest, but this task is not yet completed and posits an inviting challenge for applying new tools from the information-age, culminating in the encoding of the Mayan script. Join us Tuesday morning, September 11th, as this keynote highlights the latest milestones attained in this pursuit by the NcodeX Project, where Carlos Pallan collaborates with Dr. Deborah Anderson, Researcher, Dept. of Linguistics, UC Berkeley, the Script Encoding Initiative and members of the Unicode advisory board. Stemming from research funded by Unicode’s Adopt-a-Character Program, it has been possible to produce new database tools and advanced functionalities, capable of mapping and analyzing all the textual contents of the extant Mayan books or Codices by relying on a novel catalog of Mayan signs with assigned code points.

See What’s Happening At IUC 42

For over 27 years the Internationalization & Unicode® Conference (IUC) has been the preeminent event highlighting the latest innovations and best practices of global and multilingual software providers. Join us in Santa Clara to promote your ideas and experiences working with natural languages, multicultural user interfaces, producing and supporting multinational and multilingual products, linguistic algorithms, applying internationalization across mobile and social media platforms, or advancements in relevant standards.

Join expert practitioners and industry leaders as they present detailed recommendations for businesses looking to expand to new international markets and those seeking to improve time to market and cost-efficiency of supporting existing markets. Recent conferences have provided specific advice on designing software for European countries, Latin America, China, India, Japan, Korea, the Middle East, and emerging markets.

Adopt-a-Character

Over 130,000 characters are available for adoption, to help the Unicode Consortium’s work on digitally disadvantaged languages.

[badge]

Thursday, August 9, 2018

More Emoji Draft Candidates for 2019

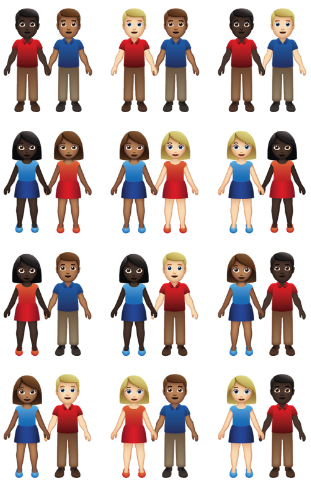
Couples Image There are now 179 proposed Emoji Draft Candidates (61 characters plus variants) for 2019. These are the short-listed candidates for Emoji 12.0, which is planned for release in 2019Q1 together with Unicode 12.0.

The following changes were made in the recent Unicode Technical Committee (UTC) meeting:
  1. Added a candidate emoji for deaf person
  2. Changed service animal vest to safety vest, and added a candidate emoji sequence using it: service dog
  3. Added candidate emoji sequences for couple holding hands, with 55 combinations of skin tone and gender
  4. Changed names and ordering for various characters
The list of draft candidates will be reviewed and finalized in the next UTC meeting, this coming September. Feedback is solicited on short names, keywords, and ordering. See also the Emoji 11.0 charts.

Eight Emoji Provisional Candidates for 2020 were also added (ninja, military helmet, mammoth, feather, dodo, magic wand, carpentry saw, screwdriver). For example:

􁌂
􁌅
ninja
magic wand

Between now and March 2019, these and other Provisional Candidates will be collected. The Unicode emoji subcommittee will then assess the whole set, and make recommendations to the UTC for which emoji to advance to Draft Candidate status for 2020.

Adopt-a-Character

Over 130,000 characters are available for adoption, to help the Unicode Consortium’s work on digitally disadvantaged languages.

[badge]

Wednesday, July 18, 2018

ICU moves to GitHub and Jira

ICU LogoInternational Components for Unicode (ICU) is a mature, widely used set of C/C++ and Java libraries providing Unicode and Globalization support for software applications. ICU is widely portable and gives applications the same results on all platforms and between C/C++ and Java software.

As of this week, ICU has moved from a self-hosted source code and bug tracking environment, to git on GitHub and Jira on Atlassian Cloud, respectively. Pull requests are welcome, as are bug reports on the new issue tracking system.

For more information, please see the following links:

ICU Repository Access: http://site.icu-project.org/repository
ICU Bug Tracking: http://site.icu-project.org/bugs

Adopt-a-Character

Over 130,000 characters are available for adoption, to help the Unicode Consortium’s work on digitally disadvantaged languages.
[badge]

Friday, July 13, 2018

Unicode 11.0 Paperback Available

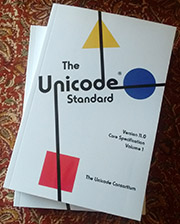
Unicode 11.0 copies The Unicode 11.0 core specification is now available in paperback book form with a new, original cover design. This edition consists of a pair of modestly priced print-on-demand volumes containing the complete text of the core specification of Version 11.0 of the Unicode Standard.

Each of the two volumes is a compact 6×9 inch US trade paperback size. The two volumes may be purchased separately or together, although they are intended as a set. The cost for the pair is US $16.58, plus postage and applicable taxes. Please visit the description page to order.

Note that these volumes do not include the Version 11.0 code charts, nor do they include the Version 11.0 Standard Annexes and Unicode Character Database, which are all freely available on the Unicode website.

Purchase The Unicode Standard, Version 11.0 - Core Specification

Adopt-a-Character

Over 130,000 characters are available for adoption, to help the Unicode Consortium’s work on digitally disadvantaged languages.

[badge]

Thursday, July 5, 2018

Unicode Consortium Announces Version 11.0 and Version 12.0 Cover Designs

The Unicode Consortium is pleased to announce the design selected for the cover of the forthcoming print-on-demand publication of The Unicode Standard, Version 11.0. The Unicode Consortium issued an open call for artists and designers to submit cover design proposals. An independent panel reviewed all submitted designs. Because of the accelerated release schedule for Version 12.0 (March 2019), the design for the print-on-demand publication of The Unicode Standard, Version 12.0 was also selected at this time.

Unicode 11.0 Books
The cover for Version 11.0 is an original design by Joyce S. Lee, a graduate student in the UC Berkeley School of Information. Her artwork was inspired by the well-known early 20th-century Bauhaus design school. She explains, “I see numerous parallels between the Bauhaus and the Unicode Consortium, including an intersection of workmanship and technological reproduction, a spirit of collaboration, as well as a widespread cultural influence. With this Bauhaus inspired cover, I thus aim to represent the Unicode Standard as a form of instructional reference for technologists around the world.”

[cover art by Monica Tang]
Cover artwork for Version 12.0 was created by Monica Tang, a computer science student at UC Berkeley. Her design was inspired by the simplicity of the geometric shapes that comprise the diversity of characters and symbols represented in the Unicode Standard. She notes, “Incorporating a variety of shapes and colors into a patterned design, I seek to convey the sheer breadth of the languages covered in the Unicode Standard as well as a sense of commonality.”

Runner-up designs by Feixiong “Hasutai” Liu and Maurice Meilleur were also selected. Hasutai is the founder and chief designer of Sir Sebsihiyan Sibe-Manchu Culture Center. Maurice Meilleur is Assistant Professor of Graphic Design at Appalachian State University.

Hasutai:
[art by Hasutai]
Maurice Meilleur:
[art by Maurice Meilleur]

Adopt-a-Character

Over 130,000 characters are available for adoption, to help the Unicode Consortium’s work on digitally disadvantaged languages.

[badge]