Friday, June 3, 2016

Encoding the Mayan Script: your Adopt-a-Character sponsorships at work

[Mayan Image] The first grant of funds from Unicode’s Adopt-a-Character program has been awarded to UC Berkeley’s Script Encoding Initiative (SEI), for the first two phases of a project to include Mayan hieroglyphs as Unicode characters.

Thanks go to our sponsors for providing funds to support this grant. Adopting a character helps the Unicode Consortium in its goal to support the world’s languages.

Mayan hieroglyphs were used from 250 BCE until the 1500s. Mayan textual records include historical, literary, religious, and mythological information, as well as a sophisticated mathematical system on par with that of the Romans. Mayan astronomical records continue to capture the attention of astronomers today. Including Mayan hieroglyphs as Unicode characters will allow them to be used on computers around the world. See more about Mayan.

Mayan is a complex script, requiring special support in layout and presentation. The first phase is a catalog and analysis of the Dresden codex, resulting in a draft set of Unicode atomic signs and composition mechanisms needed for full Mayan text. The second phase is based on that analysis: preparation of a proposal for layout and presentation mechanisms in Unicode text, using those atomic elements. These two phases are to be completed in 2017.

Wednesday, May 18, 2016

ICU joins the Unicode Consortium

ICU ProjectToday we are welcoming the ICU project into the Unicode Consortium.

Every smartphone and laptop uses the Unicode encoding and Unicode CLDR data for language support: from Arabic to Japanese to Zulu — and even plain English. The Unicode Consortium provides the data, but has not provided software to directly use that data, until now.

The ICU (International Components for Unicode) project has long provided software that implements the Unicode data and algorithms. ICU is a mature, very widely deployed set of C/C++ and Java software libraries, open-sourced since 1999 under the stewardship of IBM. When you see a date or number written in your language on your smartphone, for example, or a list of sorted names, the formatting and sorting are done with ICU.

There has long been a close working relationship between the various Unicode Consortium committees and the ICU team, with many people working on Unicode projects as well as ICU. That has ensured that Unicode data and algorithms can be effectively and quickly implemented.

IBM made the decision to transfer ICU to the Unicode Consortium so that ICU could benefit from the formal and open governance that the Unicode Consortium offers. “IBM has a long history in our commitment to open standards as a driver of innovation for our customers worldwide,” said Helena Chapman, IBM Globalization Executive. By moving ICU under the Unicode Consortium, it provides a cross-industry, open source collaboration that will drive greater consistency and interoperability across computing platforms to the benefit of global technology users world-wide. IBM has been an active member of the Unicode Consortium since its inception, and is pleased to see this further consolidation of foundational open source globalization standards.

The ICU team has become a new Consortium technical committee, along with the other Unicode committees. ICU will be released under the Unicode open-source license (similar to the previous license), just like the Unicode Character Database and the CLDR data. For users of ICU, we’ll try to make this transition as smooth as possible.

The Unicode Consortium and the ICU team would like to thank IBM for many years of project stewardship, as well as for major past and ongoing contributions to the project.

For more information, see http://site.icu-project.org/

Monday, May 16, 2016

PRI #326: Combined registration of the MSARG collection sequences

The Unicode Consortium has posted a new issue for public review and comment.

Public Review Issue #326: A submission for the “Combined registration of the MSARG collection and of sequences in that collection” has been received by the IVD registrar.

This submission is currently under review according to the procedures of UTS #37, Unicode Ideographic Variation Database, with an expected close date of 2016-08-12. Please see the submission page for details and instructions on how to review this issue and provide comments:

http://www.unicode.org/ivd/pri/pri326/

The IVD (Ideographic Variation Database) establishes a registry for collections of unique, and sometimes shared, variation sequences for CJK Unified Ideographs, which enables standardized interchange in plain text, in accordance with UTS #37, Unicode Ideographic Variation Database.

Wednesday, May 4, 2016

Not Just Emoji

Every programmer knows about Unicode. Most other people have no idea what it is, even though they use Unicode every day. Every character you type on your smartphone or laptop — and every character you read — is defined by the Unicode Consortium.

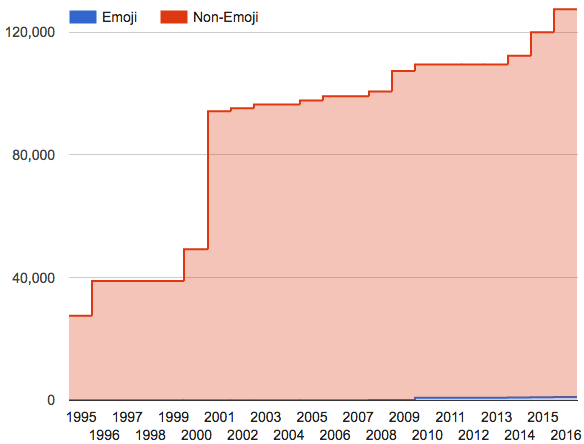
The awareness of the Unicode Consortium has grown recently, with the spread of emoji. But from the news articles, it’s easy to get the impression that emoji is the only thing we do. In reality, there are over 120,000 characters defined, and as you see below, only a small fraction of them are emoji.

Emoji and Non-Emoji

For example, this June we’ll be adding 7,500 characters — and of those new characters, fewer than 1% of them are emoji. The majority of the characters are from 6 new scripts: some in modern use, and some historic.

CLDR is the other main project for the Unicode Consortium. It provides the building blocks for supporting a variety of different languages. We’ve just released CLDR v29, and are about to start data submission for v30. Especially if you are a native speaker of a “digitally disadvantaged” language, we encourage you to join the other contributors to CLDR to help with this effort.

The Unicode Consortium is a volunteer-driven 501(c)(3) non-profit organization. Some people may work on emoji, while others work on ancient scripts, or Chinese ideographs. Others work on the language support in CLDR, or other projects.


You can help fund the work of the consortium — even if you don’t contribute technically — by adopting your favorite character through the Adopt A Character program.

— Mark Davis, President

Friday, April 15, 2016

Call for Unicode 9.0 Cover Design Art

 [cover1] The Unicode Consortium is inviting artists and designers to submit cover design proposals for Version 9.0 of The Unicode Standard. This is the first time Unicode is extending this invitation.

The cover design would appear on the Unicode Standard 9.0 web page, in the print-on-demand publication, and in associated promotional literature on the Unicode website. The chosen artist will receive full credit in the colophon of the publication, and wherever else the design appears, and receive $700. The two runner-up artists will receive $150 apiece.

Everyone in the world uses Unicode every time they read or type any character on any laptop, tablet, or smart phone. This is the opportunity to be on the cover of the standard for those characters.

Please see the announcement web page for requirements and more details.

Wednesday, March 16, 2016

CLDR Version 29 Released

CLDR CoverageUnicode CLDR 29 provides an update to the key building blocks for software supporting the world's languages. This data is used by all major software systems for their software internationalization and localization, adapting software to the conventions of different languages for such common software tasks. The following summarizes the main improvements in the release.

New BCP47 extension keys have been added for specifying transliteration and emoji presentation, and for customizing locales with region-specific settings. Many new transforms are provided, the rule format has been simplified, and BCP47 IDs have been added for all transforms. Region data now includes appropriate preferences for day periods such as “6:00 in the morning” and “7:00 in the evening”, and there is new structure for choosing appropriate units based on region and usage. A Cantonese locale has been added. The emoji ordering has been improved, and annotations are provided for more emoji and in more locales. The JSON-format data has been extended to include number spellout (RBNF) and script metadata.

The specification and charts have also been updated.

For further details and links to documentation, see the CLDR Release Notes

Tuesday, March 15, 2016

Be a Part of Our 40th Conference!

Call for Participation Now Open

 [IUC 40 Banner]

For twenty-five years the Internationalization & Unicode® Conference (IUC) has been the preeminent event highlighting the latest innovations and best practices of global and multilingual software providers. The 40th conference will be held this year on November 1-3, 2016 in Santa Clara, California.

Two Key Themes for This Year

Breaking All Barriers: Explore how software providers can meet the globalization challenges of supporting the burgeoning diversity of communication platforms around the world, including mobile, tablets, social media, video, and voice. Examine how online social platforms are supporting multilingual text and rich content in hundreds of languages. Often the task is not just to publish in multiple languages, but to accept input in alternative forms, analyze it for meaning and sentiment, look for patterns in big data, or automate its routing or translation. This theme also includes the latest advances in relevant standards, and emerging and historic scripts.

Trained, Tested, Trusted: Understand best practices in process and among teams reliably delivering high quality global products. Examine how developers build, test, and deploy great global products. Explore technologies for design, localization, multilingual testing, workflow management, and content management.

This is the conference where you can promote your ideas and experience working with natural languages, multicultural user interfaces, producing and supporting multinational and multilingual products, linguistic algorithms, applying internationalization across mobile and social media platforms, or advancements in relevant standards.

We welcome your proposals for papers and tutorials. View examples of content from past conferences on the IUC 40 website.

Thursday, March 10, 2016

Unicode 9.0 Beta Review

 [Adlam Sample Image] Mountain View, CA, USA – The Unicode® Consortium today announced the start of the beta review for the forthcoming Unicode 9.0.0, which is scheduled for release in June, 2016. All beta feedback must be submitted by May 2, 2016.

Unicode is the foundation for all modern software and communications around the world, including all modern operating systems, browsers, laptops, and smart phones – plus the Internet and Web (URLs, HTML, XML, CSS, JSON, etc.). Thus it is important to ensure a smooth transition to each new version of the Unicode Standard.

Unicode 9.0.0 comprises several additions and changes which require careful migration in implementations. These include asymmetric case mappings, numerous variation sequences, new fractional numeric values, and changes to property values, especially East_Asian_Width values. The line breaking and text segmentation algorithms handle character sequences that represent emoji as indivisible units via the addition of new property values and rules. Implementers need to modify code and check assumptions for all affected processes to support these additions and changes.

The new character repertoire includes 74 emoji symbols, 19 symbols used in Japanese TV broadcasting, and multiple additions to existing scripts. There are six new scripts, of which three are in modern use (Adlam, Osage, and Newa) and three are historic (Bhaiksuki, Marchen, and Tangut). Adlam and Osage have case pairs and require data updates for casing functions. Tangut is a large ideographic script whose addition incurred changes to the Unicode Collation Algorithm (used as the basis for sorting text in all languages).

Please review the documentation, adjust your code, test the data files, and report errors and other issues to the Unicode Consortium by May 2, 2016. Feedback instructions are on the beta page.

See http://unicode.org/versions/beta-9.0.0.html for more information about testing the 9.0.0 beta.

See http://unicode.org/versions/Unicode9.0.0/ for the current draft summary of Unicode 9.0.0.

About the Unicode Consortium

The Unicode Consortium is a non-profit organization founded to develop, extend and promote use of the Unicode Standard and related globalization standards. The membership of the consortium represents a broad spectrum of corporations and organizations, many in the computer and information processing industry. Members include: Adobe, Apple, Emoji One, EmojiXpress, Facebook, Google, Government of Bangladesh, Government of India, Huawei, IBM, Microsoft, Monotype Imaging, Sultanate of Oman MARA, Oracle, SAP, Tamil Virtual University, The University of California (Berkeley), Yahoo!, plus well over a hundred Associate, Liaison, and Individual members. For more information, please contact the Unicode Consortium http://www.unicode.org/contacts.html.